Log in

The show of support by Jewish voters for Dr. Abdul El-Sayed appears aimed at countering a push from other Jews in Michigan who oppose him or are threatening to.


|
Pragmatic idealist. Worked on Ubuntu Phone. Inkscape co-founder. Probably human.
|

The popular fluffy steamed buns are filled with pork, vegetables, tofu — and in one trendy Beijing shop, chocolate and red beans.


For years, Microsoft and OpenAI have fought to keep certain information out of the public eye in their fight with news organizations that have accused the AI firms of teaming up to violate copyright laws by stealing tons of news content to train AI.
However, now the details that should never have been marked confidential are starting to leak. In a motion for summary judgment that was unsealed Thursday from news plaintiffs led by The New York Times, internal documents are exposed that news groups alleged show exactly how Microsoft and OpenAI viewed the threat to news before unleashing new AI products like ChatGPT and Copilot.
Perhaps most explosively, Microsoft Director of Applied Science Brent Hecht repeatedly warned in documents that scraping news for AI training was “an astonishing theft of unprecedented proportions,” calling it perhaps the “largest theft of labor in human history,” news orgs said. In another document, Hecht contradicted Microsoft and OpenAI’s argument that training AI on news content is fair use, suggesting that the plan to widely scrape news made “a complete mockery of the idea of ‘fair use.’”
Over at OpenAI, ChatGPT head Nick Turley wrote in an internal message that publishers would face an “existential threat” from commercial products trained on news content that can be used to substitute news providers. One Microsoft document even described a “doom loop,” news orgs said, “that will hurt the performance of our models and the entire web at the same time.”
“It is highly unusual that an end-product threatens the economic foundations of its essential suppliers, but that is the situation we have created for our LLM business with respect to its ‘content supply chain,’” that document said.
Data from both firms shows that this prediction was accurate. Microsoft recorded 83–93 percent drops in click-through rates for some news plaintiffs, and 51–94 percent drops for others. Add to that reporting on low click-through rates from ChatGPT search results and news organizations’ own reporting on traffic declines. Suddenly, it becomes easier to see how declining news revenue could ultimately rob chatbots of the abundant streams of reliable information that supposedly makes them such groundbreaking tools.
Meanwhile, “almost no one intended for content they created to be used in this fashion, nor are they compensated for its use,” Hecht acknowledged in a Microsoft document.
News organizations say they’re ready to go to trial because there’s so much “compelling evidence of substitution.” If they can prove that chatbots are replacing them in their own markets, while serving to spit out excerpts of articles verbatim, they think that one-two punch may eviscerate Microsoft and OpenAI’s fair use arguments.
“The future not just of journalism but of responsible AI too depends on preserving incentives for humans to produce the creative works on which a healthy society depends,” news groups argued.
Under oath, Microsoft CEO Satya Nadella testified that AI companies shouldn’t be violating news sites’ terms of use by dodging paywalls. But over at OpenAI, internal messages showed that when a staffer, Nick Ryder, informed President Greg Brockman that “a hack” was found for OpenAI crawlers “to get around” the NYT paywall, Brockman replied, “Ah, nice.”
Nadella also acknowledged that chatbots have served as substitutes for news platforms, describing the chatbot as stealing clicks from news sites by “giving you the information right there on the website on the AI platform versus needing to go to the underlying source.”
There’s consensus on that at OpenAI, where a software engineer said in an internal message that “no matter how prominently we show the links, users won’t click.”
OpenAI’s Turley agreed that there is “no good reason to click” when the chatbot provides information, the motion said. He also seemingly suggested that the doom loop was already in motion, describing chatbots as “largely substitutive, period” and predicting that they “will get more and more substitutive as they get better.”
News groups argued that insiders' own statements should be damning.
“With respect to outputs that are substantially similar to training or grounding sources, courts have rejected claims that copying news articles to provide a product that substitutes for demand for news is fair use,” news groups argued.
News groups tried many different tactics to test if Microsoft and OpenAI products would output their news articles verbatim. Their motion shows they went further than early strategies where they would ask chatbots to provide access to entire news stories by repeatedly asking “what’s the next line?”
In some cases, news organizations found that chatbots would generate long excerpts of articles when users requested summaries of articles. Other flagged outputs were generated by asking for key bullet points of articles. Particularly successful were prompts requesting that chatbots “rate the bias” of news articles. Chatbots also reproduced portions of articles if users asked them to pick any article off a certain site’s homepage.
In their motion, news plaintiffs have only asked the court to rule on infringed articles where outputs “demonstrate extensive verbatim overlap,” because they’re confident that the “substitutive purposes of defendants’ copying weigh against fair use.” Legal concerns with other articles will be raised at trial, they said.
OpenAI did not immediately respond to Ars’ request to comment.
However, a Microsoft spokesperson defended Microsoft’s AI products as a transformative fair use that don’t substitute for news sites. The spokesperson said that Nadella’s testimony touched on “broad principles and changes underway in how people find and consume information,” which were merely “observations” that “should not be confused with conclusions about copyright questions before the Court, which Microsoft addresses in its filings.”
Regarding Hecht’s comments, the spokesperson claimed that those documents only “reflect one employee’s individual perspective, are not a legal analysis, and do not represent the company’s views.”
Steven Lieberman, counsel for the New York Daily News and seven of its sister papers, disagrees. He told Ars that “the evidence revealed here for the first time shows that OpenAI and Microsoft knew that what they were doing was wrong.”
“Throughout this case Defendants insisted that these documents be treated as confidential so that the public could not see them,” Lieberman said. “Well, now the cat is out of the bag. Finally, the world can see what OpenAI and Microsoft thought all along about the fairness of their own behavior.”
News plaintiffs have argued that regardless of the individual expressing the views, the internal documents make clear that firms anticipated that verbatim outputs would harm news sites. Further, they alleged that instead of preventing the outputs, the firms tried to make it harder for news groups to test chatbots by creating a filter that Hecht suggested could be perceived as an “accidental cover up” because it would result in “people who have a right over the content having less visibility into what was used for training."
News groups are also upset that instead of listening to insiders warning that scraping news was theft, Microsoft and OpenAI never chose to license content, allegedly usurping them in another market in ways they couldn't anticipate.
Specifically, their motion accused Microsoft of violating “industry norms” by selling a dataset purchased for Bing as training data for OpenAI, allegedly doing so without consulting news groups that would not have approved of that repurposing of their consent to basic search engine crawling. Further, OpenAI allegedly “acted improperly” by obtaining a NYT dataset with 1.8 million articles from a third party that was bound to an agreement that the data wouldn’t be used for commercial purposes. OpenAI’s employees knew it “would not be appropriate” to use that data “to train a model,” but they did it anyway, news groups alleged.
For news groups, the problem isn’t just Microsoft and OpenAI, but all the AI firms that are following their lead in "free-riding" on their content, the motion said. Most notably, after ChatGPT’s launch, Google’s AI Overviews was quickly introduced and started absorbing even more traffic that previously went to news sites.
If courts don’t clarify that AI firms must license news content, both news publishers and AI firms could be doomed, news plaintiffs argued. One Microsoft internal document agreed that “there is a ‘real risk’ that GenAI could ‘significantly disrupt’” the “employment of the very people who generated the data on which the foundation model was trained,” they noted. Microsoft even included a cartoon illustrating the problem of LLMs destroying their own supply chains, they said:
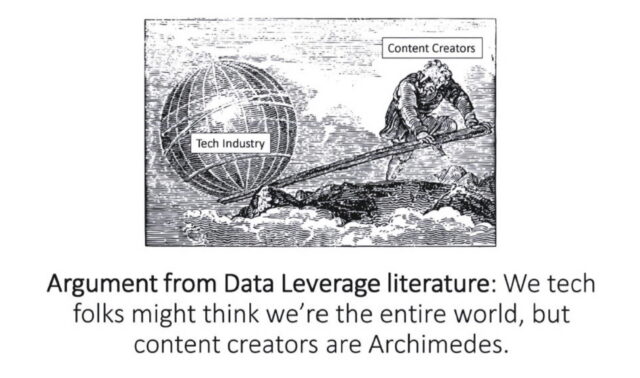 Cartoon in a Microsoft internal document.
Credit:
via News Plaintiffs
“AI companies remain powerless to break out of this ‘doom loop,’ because, while the industry as a whole would benefit if every company paid to sustain the continued production of the creative works their technology depends on, each individual company is better off taking content for free while others pay,” news groups argued.
As evidence of this blind greed, their motion emphasized that Brockman wrote that he was “deeply motivated by the gazillions” that could be gained by commercializing OpenAI’s technology.
“Finding that copying news for AI is not fair use would solve this prisoners’ dilemma by putting all AI companies, OpenAI and Microsoft included, on an even footing,” news organizations said.
This story was updated with a quote from New York Daily News counsel Steven Lieberman.